Worth pointing out that you can run models locally on consumer hardware that are as good as frontier models from ~3 months ago (and that gap is getting smaller and smaller) which solves ever single problem listed in this post
Does it link to the internet and do I have to let it access every part of my life?
Idk man in a surveillance state, AI seems like the most obvious way into everyone’s lives that’s ever been deployed by companies who are awful and shamelessly so.
For the case of local models, no not at all. Most local models are under a free license (or at least a non-commericial one) and it all runs locally on your hardware, however what you can run and how well depends on your hardware and some software fiddling. Non-local stuff if 100% a ploy to make everyone dependent on big tech even more than they already are, though
Qwen 3.8 has a 27b (consumer gpu) model and one that will run in 128gb. deepseek 4.1, glm 5.3 flash, and mimo 2.6 flash also fit in 128-256gb ram, and challenge models for 1-2 months ago.
depends who wants to setup a local model and be responsible for it
it gets to a point where isn’t a youtube to help any further, and you end up making it up as you go along
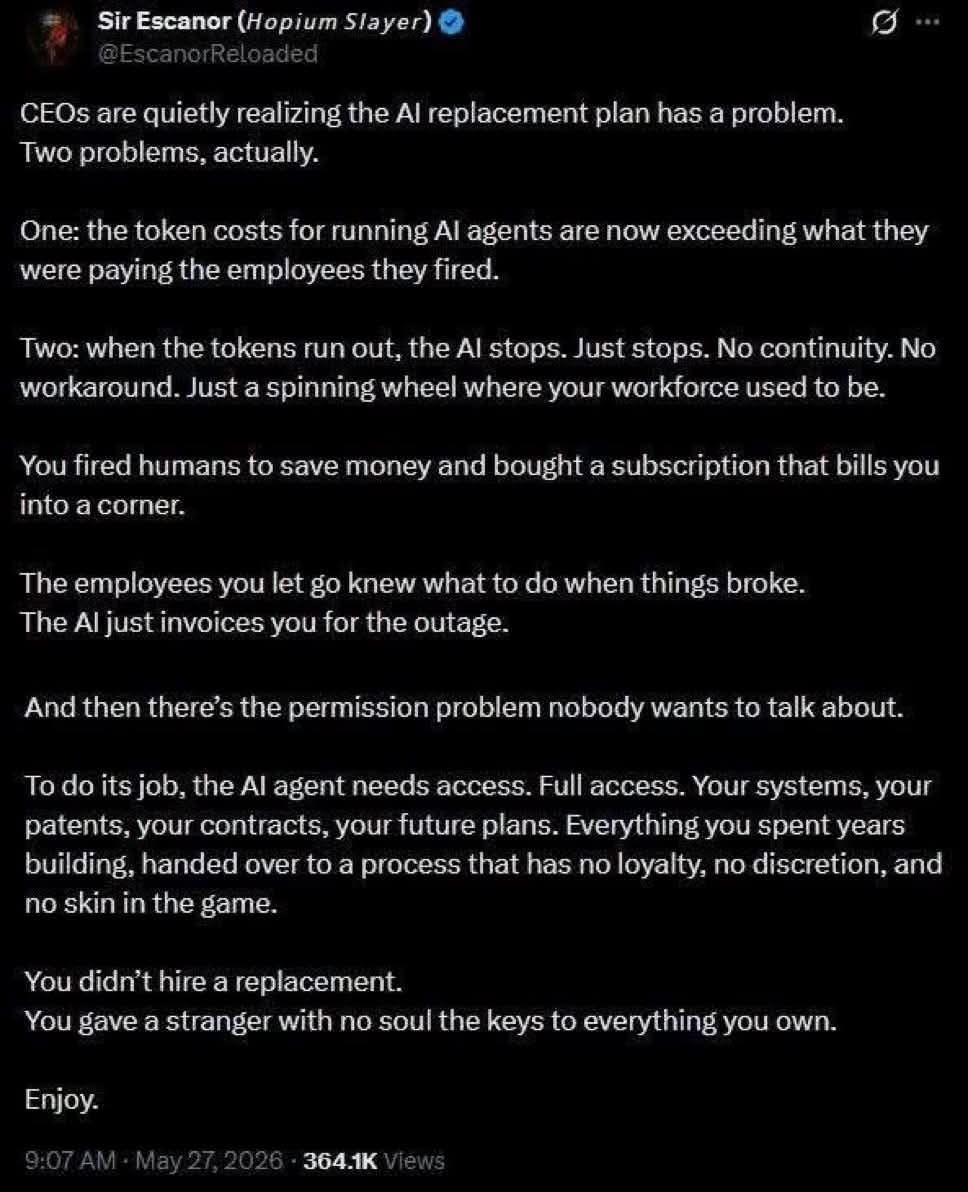
Worth pointing out that you can run models locally on consumer hardware that are as good as frontier models from ~3 months ago (and that gap is getting smaller and smaller) which solves ever single problem listed in this post
Does it link to the internet and do I have to let it access every part of my life?
Idk man in a surveillance state, AI seems like the most obvious way into everyone’s lives that’s ever been deployed by companies who are awful and shamelessly so.
For the case of local models, no not at all. Most local models are under a free license (or at least a non-commericial one) and it all runs locally on your hardware, however what you can run and how well depends on your hardware and some software fiddling. Non-local stuff if 100% a ploy to make everyone dependent on big tech even more than they already are, though
What are some local models worth exploring?
Qwen 3.8 has a 27b (consumer gpu) model and one that will run in 128gb. deepseek 4.1, glm 5.3 flash, and mimo 2.6 flash also fit in 128-256gb ram, and challenge models for 1-2 months ago.
128 GB RAM? In this economy ?
depends who wants to setup a local model and be responsible for it it gets to a point where isn’t a youtube to help any further, and you end up making it up as you go along